- Cerebras published a technical breakdown of how it deploys trillion-parameter models across its WSE-3T wafer-scale chips, using the open-source, ~3-trillion-parameter Kimi K3 model as its example.
- Each WSE-3T wafer has 44GB of on-chip memory; at 4-bit quantization, Kimi K3‘s 93 layers average about 16GB each, meaning most layers fit entirely on a single wafer.
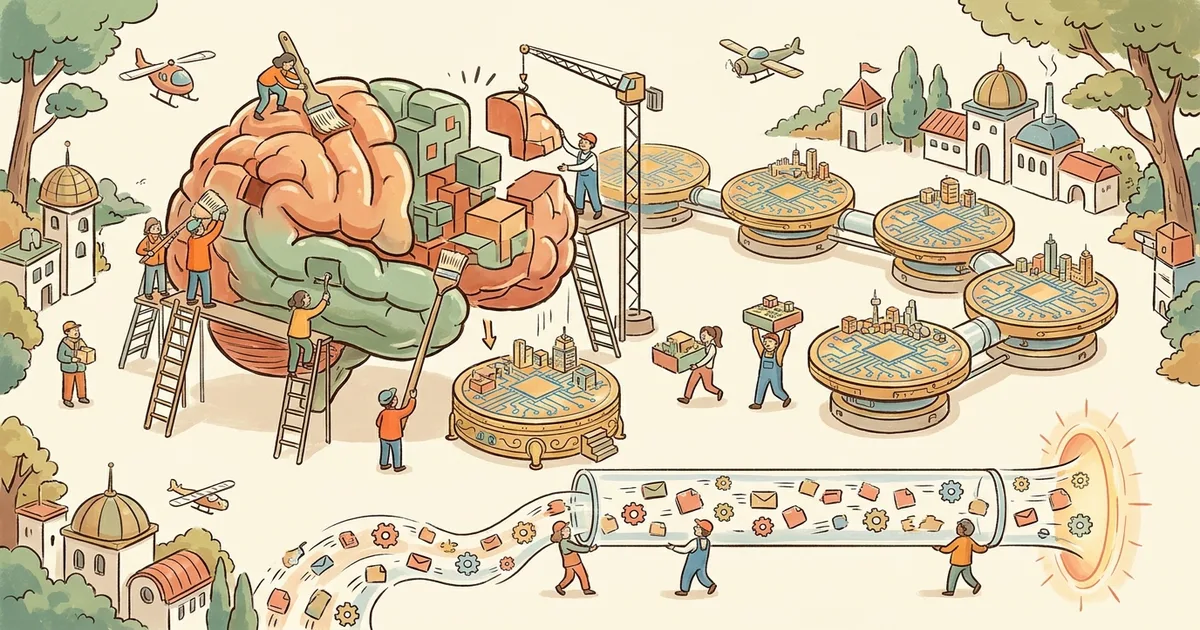
- Cerebras calculates it needs 59 wafers total for Kimi K3: one wafer per dense layer (24 wafers) to leave room for KV cache, and two linear-attention layers per wafer for the remaining 69 layers (35 wafers).
- The company says the resulting pipeline runs multi-trillion-parameter models at 1,000-2,000+ tokens per second, with only activations — not model weights — moving between wafers over RDMA at roughly 2 microseconds per hop.
What Happened
Cerebras engineer Sarah Chieng published a deployment walkthrough on October 22, 2026, explaining how the company maps frontier-scale models onto its wafer-scale hardware, using the open-source Kimi K3 model as a worked example.
Why It Matters
Trillion-parameter models need far more memory than any single chip can hold, so how a vendor splits a model across hardware directly determines both inference speed and how many user requests it can serve simultaneously. Cerebras is making its specific math public rather than treating the deployment process as proprietary.
Technical Details
Kimi K3 has roughly 3 trillion parameters across 93 layers (69 linear-attention, 24 dense). Because dense layers need on-chip room for a KV cache that scales with every active request, Cerebras places one dense layer per 44GB wafer. Linear-attention layers need no such cache, so two fit per wafer. That split yields 59 wafers total, connected in a pipeline where each wafer processes its layers and passes only activations to the next, letting different requests occupy different pipeline stages simultaneously rather than running one at a time. Cerebras notes Kimi K3 scores 88.3% on Terminal-Bench 2.1 and 91.2% on BrowseComp, close to GPT-5.6 Sol’s 88.8% and 90.4% on the same tests, which it says demonstrates frontier-level agentic performance from an open-weight model.
Who’s Affected
Teams evaluating wafer-scale inference against GPU clusters — including rivals like Nvidia and newer entrants like Tenstorrent — now have a concrete memory-and-throughput model to compare against, and developers running large open-weight models get a public reference for how much hardware a given model size actually requires. The walkthrough also comes as Cerebras works through its own supply deals, including a $20 billion commitment from OpenAI.
What’s Next
Cerebras frames the walkthrough as a template rather than a one-off, suggesting similar wafer-count math will apply as it and competing chipmakers take on even larger open-weight models.