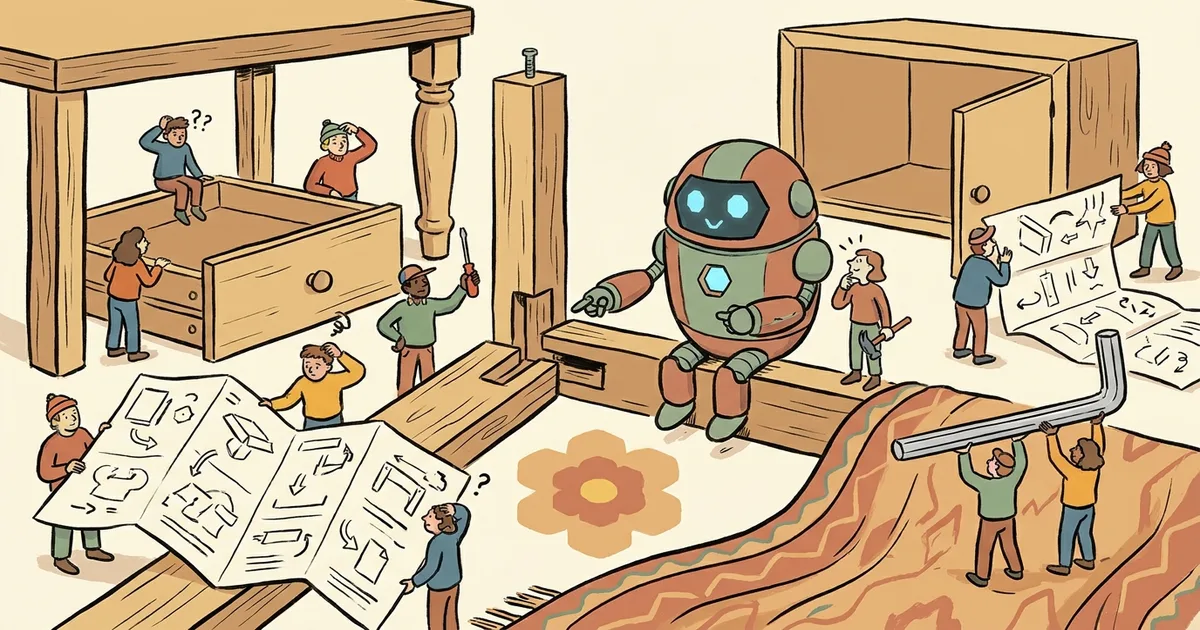
- Epoch AI’s Furniture Assembly Benchmark tests whether models can spot errors in furniture builds from photos.
- OpenAI‘s GPT-6 Astra can identify whether and where an IKEA piece was assembled wrong.
- The task probes fine-grained spatial reasoning, a longtime weakness of vision models.
- Everyday physical-error diagnosis is a practical bar few benchmarks have measured.
What Happened
OpenAI‘s GPT-6 Astra can look at a photo and tell whether an IKEA furniture piece was assembled incorrectly — and exactly where the build went wrong — according to results from Epoch AI’s Furniture Assembly Benchmark, The Decoder‘s Manuel Uth reported on September 26, 2026.
Why It Matters
Spatial reasoning about the physical world has been the persistent gap between vision-language models’ benchmark scores and their everyday usefulness. Diagnosing a mis-assembled shelf requires comparing an intended structure against a photographed one and localizing the specific error — the same skill underlying repair guidance, quality inspection, and eventually robot manipulation. An independent benchmark from Epoch AI, rather than a vendor demo, gives the claim measurement weight.
Technical Details
The Furniture Assembly Benchmark uses real assembly scenarios where the model must judge correctness from images and point to the failure — not merely caption what it sees. Error localization is the hard part: it demands part-level correspondence between instructions and the built object. Benchmark scores across other models, and failure cases, are the details worth reading in Epoch’s full results.
Who’s Affected
Consumers get a preview of genuinely useful visual assistance — point a camera, get told what’s wrong. Robotics and inspection developers gain evidence that frontier vision models can support error detection. Rival labs get a new public benchmark to chase.
What’s Next
Watch how other frontier models score on the same benchmark and whether the capability holds outside curated test sets. The gap between spotting a mistake and guiding a fix step-by-step is the next measurable rung.